
Hello! I am back for the fourth and final iteration of my journey: Cracking the Code of OSCAL’s Technical Architecture! In our previous episode, we took a deep dive under the hood to see how OSCAL’s modular building blocks talk to one another. We wrote a Python sync engine that used unique UUIDs as “digital glue” to inherit control narratives from a Component Definition and automatically update our System Security Plan (SSP). We even wired up the POA&M model so our documentation would dynamically change state—demoting controls to under-remediation whenever an open POA&M was detected.
Now that we’ve mastered the internal mechanics of the OSCAL stack, it’s time for the ultimate step: connecting our compliance engine to live, external technical evidence.
In today’s post, we are evaluating an Infrastructure-as-Code (IaC) repository to satisfy select controls from the NIST SP 800-53 catalog. The goal is to move past static “screenshot audits” and show assessors how version-controlled code proves the real-time configuration baselines of your system.
And for this special finale, I am thrilled to be joined by my close colleague, Daniella Efrach! Daniella brings a sharp, real-world perspective on deploying OSCAL in modern cloud environments, and she’ll be sharing key insights on how cloud resource configurations can be ingested into the OSCAL stack to provide real-time evidence of compliance in the cloud!
Daniella has also done research and published a blog surrounding AI and how it is changing the cyber threat landscape. It is a fantastic read and I highly recommend checking it out. It can be found on the Dark Wolf blog page or just follow this link: Artificial Intelligence is Changing the Cyber Threat Landscape.
With all that said, to tie a bow on this entire journey, we will:
Now strap in because we are going out with a bang. So let’s dive into the lab one last time!
If you’ve spent more than five minutes in the cloud world, you know IaC (Infrastructure-as-Code) is how the magic happens. Instead of clicking around in the AWS console 200 times, we write code (usually Terraform) to spin up our resources. The best part? It lets us lock down our security baselines right at the moment of creation.
For compliance, this is huge. It means we have actual code evidence proving that every single resource deployed by our pipeline is secure by default—no sketchy screenshots or hand-waving required!
To test this out in our lab, we’re using a super straightforward Terraform file named main.tf. It spins up an Amazon S3 bucket along with its public access block settings. Notice how we can flip these settings between true and false to simulate a passing or failing security check:
main.tf
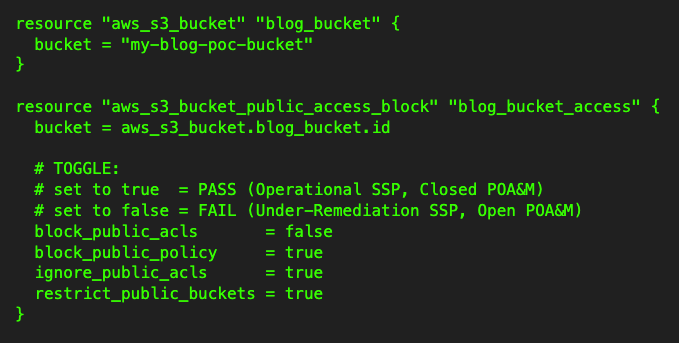
AWS gives us four different toggles here, but to keep things clean and show off how our sync engine evaluates code in real-time, we’re going to zero in on that block_public_acls setting.
Just like in my last post, we’re juggling the core three OSCAL models: the Component Definition, the POA&M Model, and the SSP.
The huge plot twist this time around? Instead of blindly copying technical narratives from the Component Definition into the SSP, we verify the code first. Our script inspects main.tf to check if our actual infrastructure matches our security baseline.
under-remediation.operational.This gives engineering teams, Assessors, and Authorizing Officials (AOs) real-time, automated verification of a system’s true security posture.
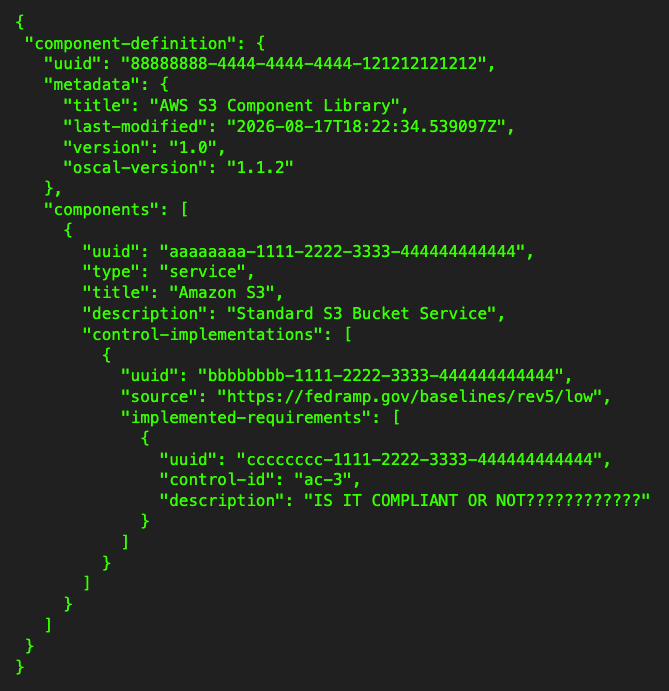
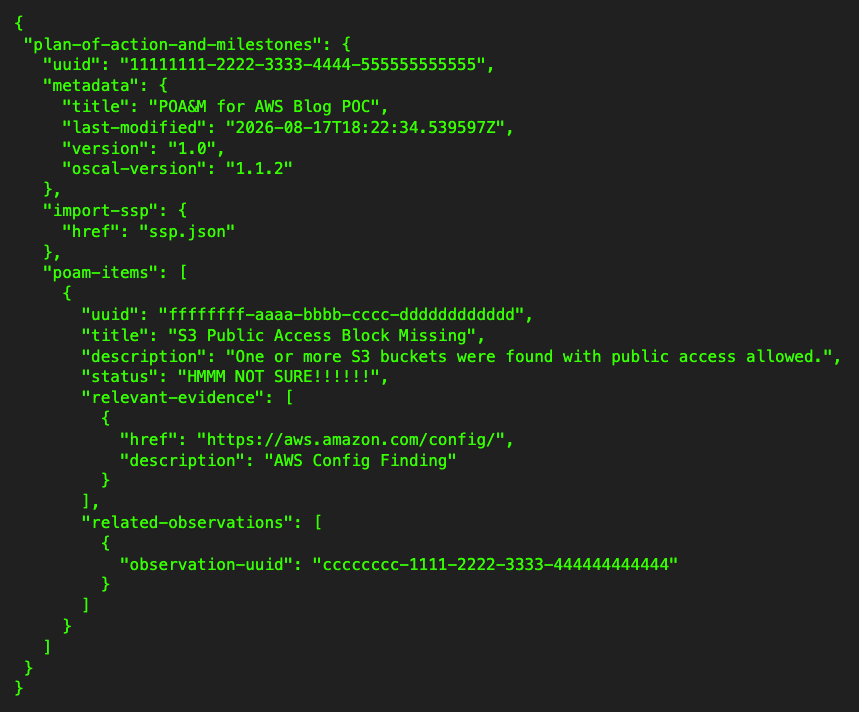
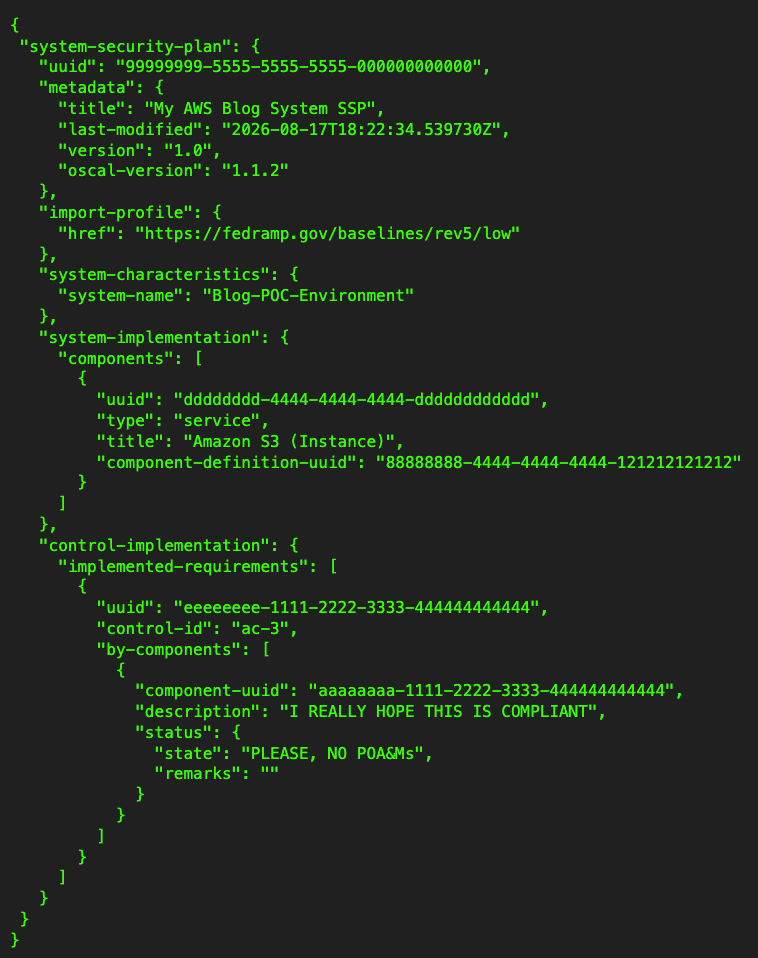
Here are our three starting OSCAL files loaded up with placeholder text so we can see the sync engine work its magic:
Now let’s take a look at the two star features of our iac_sync.py engine!
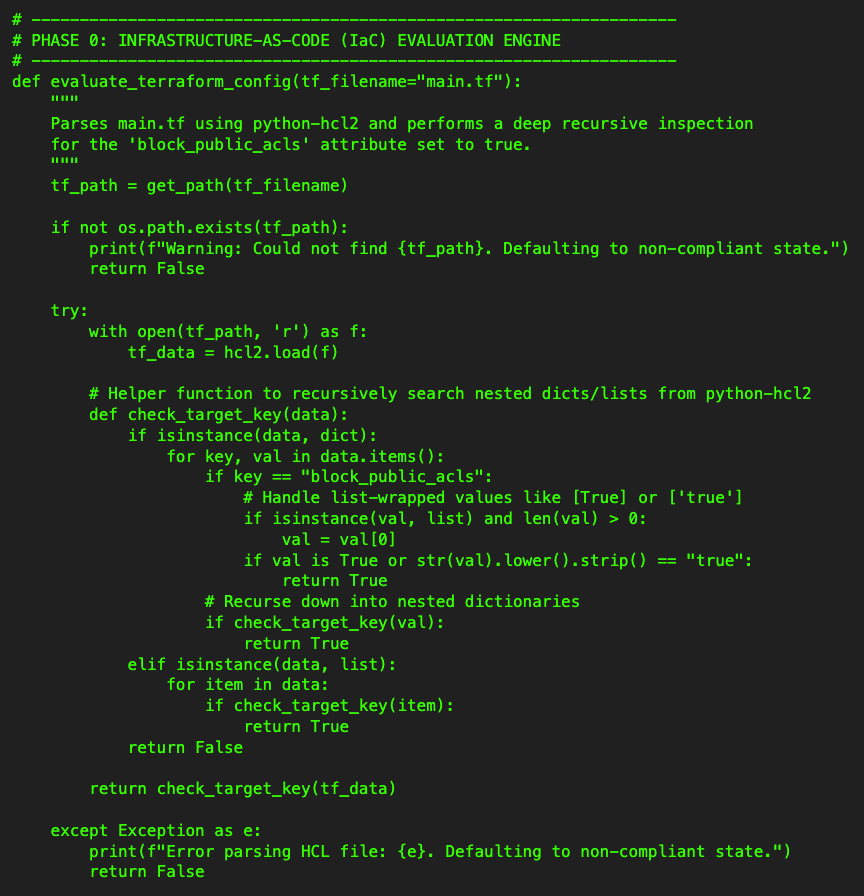
First, we load main.tf using python-hcl2. If the file is missing, we play it safe and fail closed (defaulting to non-compliant). If the file exists, our recursive check_target_key function walks the HCL dictionary tree searching for block_public_acls to see if it’s explicitly set to true:
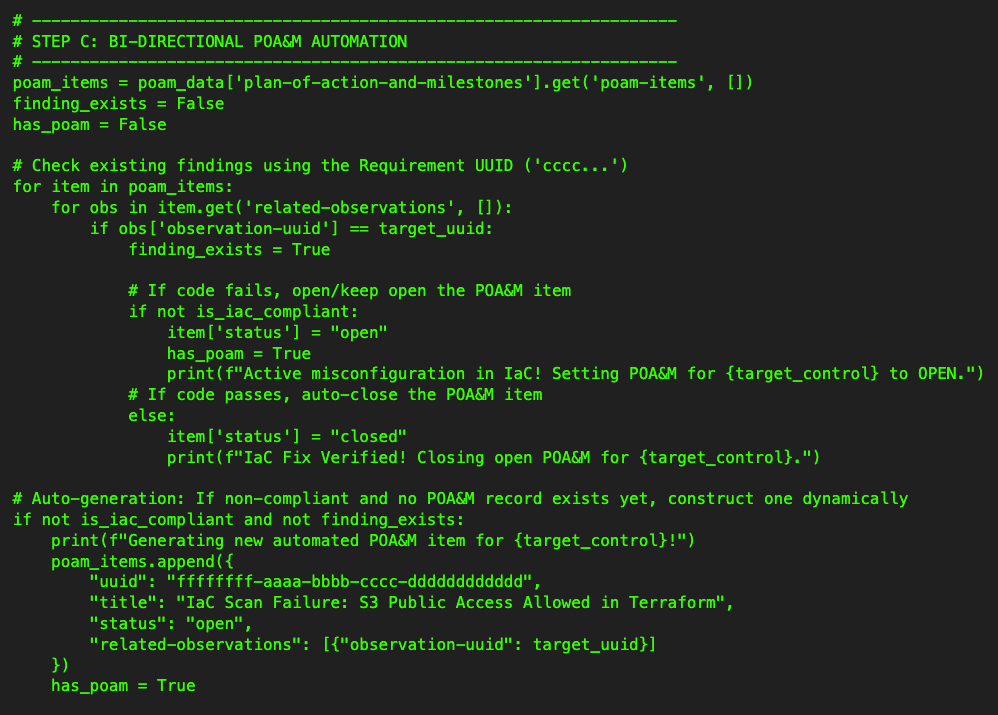
Here is where the magic happens. Based on whether is_iac_compliant returned True or False, our engine manages the weakness lifecycle:
False): It updates an existing POA&M item to “open” (or creates a brand new one if none exists).True): It automatically flips the POA&M status to “closed“.
Let’s test a non-compliant state first. With block_public_acls = false set in main.tf, we fire up our script:
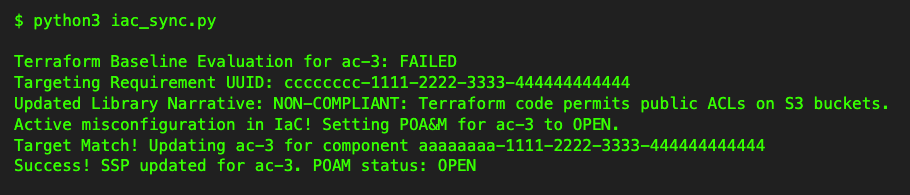
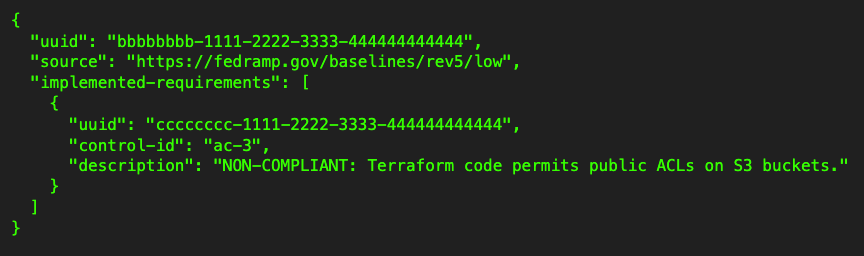
Look at how our OSCAL models reacted in real-time:
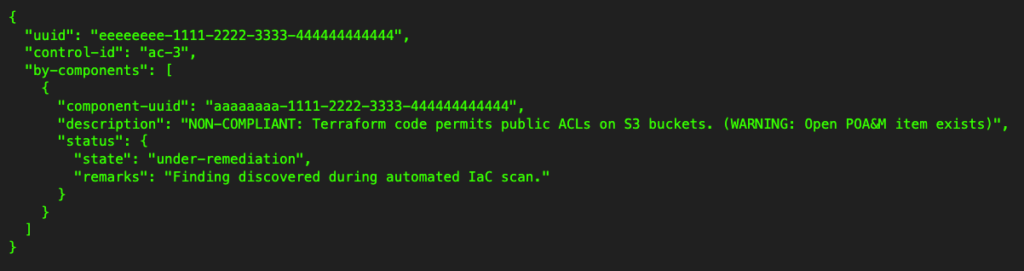
component-def.json (Library narrative flagged):
ssp.json (Demoted to under-remediation with warning string):
Now let’s fix the Terraform code in main.tf by setting block_public_acls = true and re-running iac_sync.py.
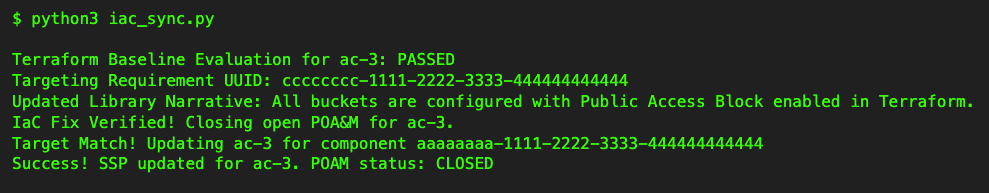
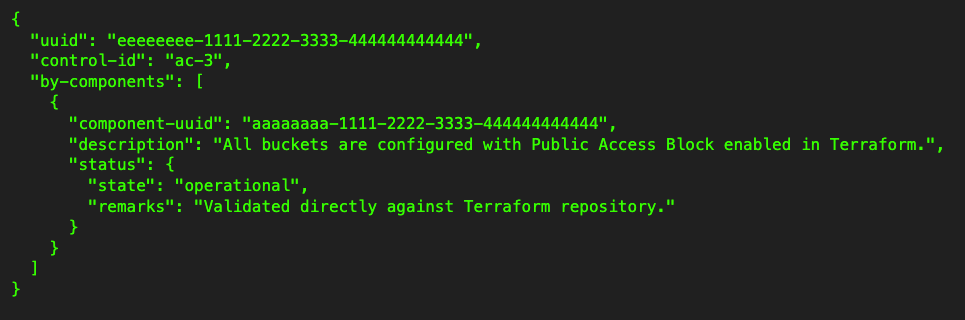
Boom! Check out how the pipeline automatically repaired our compliance documentation:
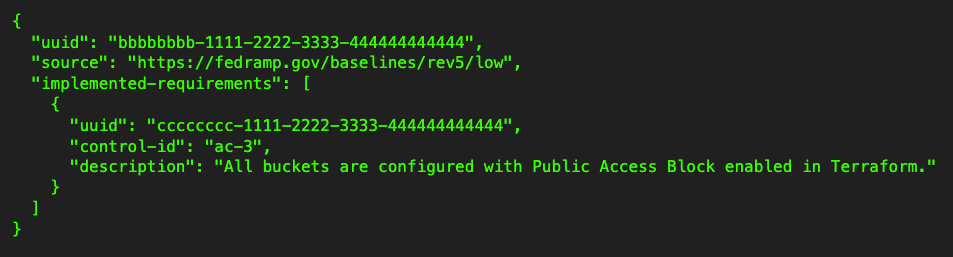
component-def.json (Updated with compliant narrative):
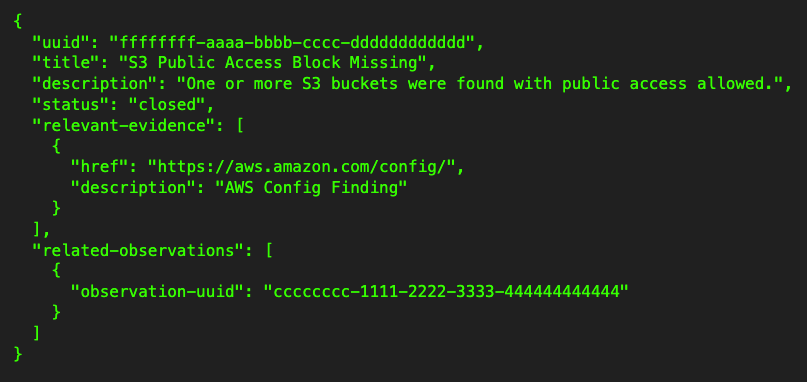
poam.json (Auto-closed finding):
ssp.json (Promoted back to operational):
Now, as promised, I’d like to hand the (blog) mic to my colleague, Daniella Efrach to give us a little more insight on how OSCAL can be operationalized in a cloud environment!
Thanks for the incredible introduction, Carl! I am so excited to jump in. For those of you who don’t know me, I’m a Cloud Engineer centered on Google Cloud, with a specialized interest in automated governance, and cloud architecture scaling. My focus is simple: eliminate compliance friction by embedding NIST SP 800-53 and FedRAMP controls directly into the software engineering toolkit.
The Python engine we just looked at is a brilliant illustration of a much larger concept. When we talk about deploying OSCAL in the real world, we aren’t just talking about changing file formats. We are talking about a fundamental paradigm shift in how an organization handles compliance.
Historically, compliance has been a massive source of friction. It usually involves a panicked, point-in-time scramble where engineers are forced to stop building and start taking screenshots of cloud consoles to prove a control is met. It is static, exhausting, and immediately outdated the moment a new deployment goes out. By shifting to an automated compliance process, we turn that entirely on its head. Here is what happens when you scale this technical architecture to the enterprise level:
Ultimately, automating compliance means security and engineering teams finally speak the same language. Assessors get irrefutable, continuous evidence, and engineers get to focus on what they do best: building great infrastructure.
The Good: The Vision is Spot On Conceptually, OSCAL is exactly what the industry needs. The idea of transforming static, siloed compliance documentation into a dynamic, machine-readable format is brilliant. As we just saw with our Python sync engine, when you connect infrastructure-as-code to an OSCAL model, the potential for true, automated compliance is undeniable. It bridges the gap between what engineers build and what auditors review.
The Bad: The Knowledge Gap The Reality? We are still far from widespread adoption, primarily because of a massive industry knowledge gap. OSCAL is not just a simple JSON file; it is a deeply nested, highly relational data model. To use it effectively, you need a hybrid skill set. Security and compliance professionals often lack the software engineering background required to manipulate the data models, while software engineers typically don’t have the deep NIST 800-53 or FedRAMP expertise to map the controls accurately. Right now, it feels like two different worlds trying to read the same dictionary.
The Ugly: The Tooling Desert The ugliest truth right now is the sheer amount of custom tooling required to make OSCAL a reality. To make our simple S3 bucket example work today, we couldn’t just plug in an off-the-shelf product, we had to build a custom iac_sync.py engine from scratch to parse the HCL and map the UUIDs. While the underlying OSCAL framework is solid, the ecosystem of vendor-agnostic, native middleware that actually connects cloud APIs (like Google Cloud SCC or AWS Config) to these OSCAL files is still in its infancy. Until more “out-of-the-box” orchestration tools emerge, organizations are burdened with building and maintaining their own connective tissue.
OSCAL is undoubtedly the future, but right now, we are in the messy middle of getting there.
A massive thank you to Daniella! Her insights were the exact spark this series needed to end with a bang and showcase the true, real-world implications of OSCAL.
I couldn’t agree more with her take on The Good, The Bad, and The Ugly of OSCAL. The realization that the cybersecurity industry is currently living in the “Messy Middle” resonated with me deeply as I worked through this hands-on lab. Getting validation and perspective from a fellow cybersecurity professional—and sharing it with all of you—has been one of the highlights of this project.
Now, building on Daniella’s reflections, here are my raw, unfiltered takeaways from this four-part journey:
I want to say thank you from the bottom of my heart for joining me on this four-episode journey! Exploring the technical mechanics, wrestling with JSON structures, and building live Python sync engines alongside you has been an incredible experience.
I hope this series inspired you to get your hands dirty, break some code in your own lab, and rethink what continuous compliance can look like.
I can’t wait to take you along on my next adventure down the road. Until next time—stay curious, keep automating, and keep leveling up!